How Much RAM Do I Need to Run an LLM Locally? (Simple 2026 Guide)
A simple, no-jargon guide to how much RAM you need to run a local LLM: the one formula to remember, a table for 8 GB to 64 GB machines, why context length eats memory, and how to check your own PC in one click.
Awareness · 10 min
How Much RAM Do I Need to Run an LLM Locally? (Simple…
A simple, no-jargon guide to how much RAM you need to run a local LLM: the one formula to remember, a table for 8 GB to 64 GB machines, why context length eats memory, and how to check your own PC in one click.
Definition
To run an LLM locally you need enough free memory to hold the model file plus a working buffer for the conversation. For a typical 4-bit (Q4) model, plan on roughly 0.7 GB of RAM per billion parameters, plus 1–2 GB for your operating system and apps.
“Will this model run on my computer?” is the first question everyone asks about local AI—and most answers online are either too technical or just wrong.
The good news is that the maths is simple once you know two things: how big the model file is, and how long your conversations are.
This guide gives you one rule of thumb, a ready-made table, and a quick way to check your exact machine.
The short answer
Typical 4-bit (Q4_K_M) GGUF models. Leave room for your OS and browser too.
| Your RAM | Comfortable model size | Good examples | Experience |
|---|---|---|---|
| 8 GB | 1–4B | Llama 3.2 3B, Qwen 2.5 3B, Phi-4 Mini, Gemma 3 4B | Good for chat, notes, and simple code help |
| 16 GB | 7–8B | Qwen 2.5 Coder 7B, Llama 3.1 8B, Mistral 7B | The sweet spot for most people |
| 32 GB | 13–14B (some ~30B) | Qwen 2.5 14B, Qwen 2.5 Coder 14B | Noticeably smarter, slower on CPU |
| 64 GB+ | 30–70B | Qwen 2.5 32B, Llama 3.3 70B (Q4) | Workstation territory; needs patience without a big GPU |
tip
Don’t want to do maths?
Quietly’s Device scan (Settings → Engine → Device scan → “Scan my device”) reads your RAM, GPU, and CPU and labels every catalog model as Best match, Good fit, May be slow, or Not recommended.
Why models need so much memory
An LLM is basically a giant list of numbers called parameters (or weights). A “7B” model has about 7 billion of them. To answer you, the computer has to read through those numbers again and again, so they all have to sit in fast memory—RAM or GPU memory (VRAM).
How much space each number takes depends on quantization, which is a kind of compression. Most local models use 4-bit versions, which are about a quarter of the original size and still give good answers.
Approximate file size of a 7B model at different quality levels.
| Format | Bits per weight (approx.) | 7B file size | Quality |
|---|---|---|---|
| FP16 (original) | 16 | ~14 GB | Reference |
| Q8_0 | 8.5 | ~7.5 GB | Near-identical |
| Q5_K_M | 5.7 | ~5 GB | Excellent |
| Q4_K_M | 4.8 | ~4.5 GB | Very good — the usual default |
| Q3 / Q2 | 2.5–3.5 | ~2.5–3.5 GB | Noticeably worse |
The one formula to remember
Take the model’s file size and add about a third on top for the working memory, plus half a gigabyte for the engine. That is close to what Quietly’s Device scan uses internally (file size × 1.1 × 1.25 + 512 MB).
Worked examples using the rule of thumb.
| Model | File size (Q4) | RAM the model needs | Good fit on… |
|---|---|---|---|
| SmolLM2 1.7B | ~1 GB | ~2 GB | Almost anything |
| Llama 3.2 3B | ~2 GB | ~3.3 GB | 8 GB laptops |
| Qwen 2.5 7B / Llama 3.1 8B | ~4.7 GB | ~7 GB | Fits 8 GB tightly; comfortable on 16 GB |
| Qwen 2.5 14B | ~9 GB | ~13 GB | 16 GB tightly; comfortable on 32 GB |
| Qwen 2.5 32B | ~20 GB | ~28 GB | 32 GB tightly; comfortable on 64 GB |
warning
Your OS needs RAM too
Windows or macOS plus a browser can easily use 4–6 GB. On an 8 GB laptop, a 7B model technically “fits” but may push the system into swap, which makes everything crawl. Close heavy apps or choose a 3–4B model.
The hidden cost: context length
Context is how much text the model can “see” at once—your question, the chat history, and any files you attach. The engine stores that text in a memory buffer called the KV cache, and it grows with every token.
For a typical 8B model, every 1,000 tokens of context costs roughly 128 MB. So an 8K context adds about 1 GB, and a 32K context adds about 4 GB on top of the model itself. That is why a model that loads fine can suddenly slow down when you paste a long document.
Approximate extra memory for context on an 8B-class model (standard 16-bit cache).
| Context | Roughly | Extra memory |
|---|---|---|
| 4K tokens | ~10 pages | ~0.5 GB |
| 8K tokens | ~20 pages | ~1 GB |
| 16K tokens | ~40 pages | ~2 GB |
| 32K tokens | ~80 pages | ~4 GB |
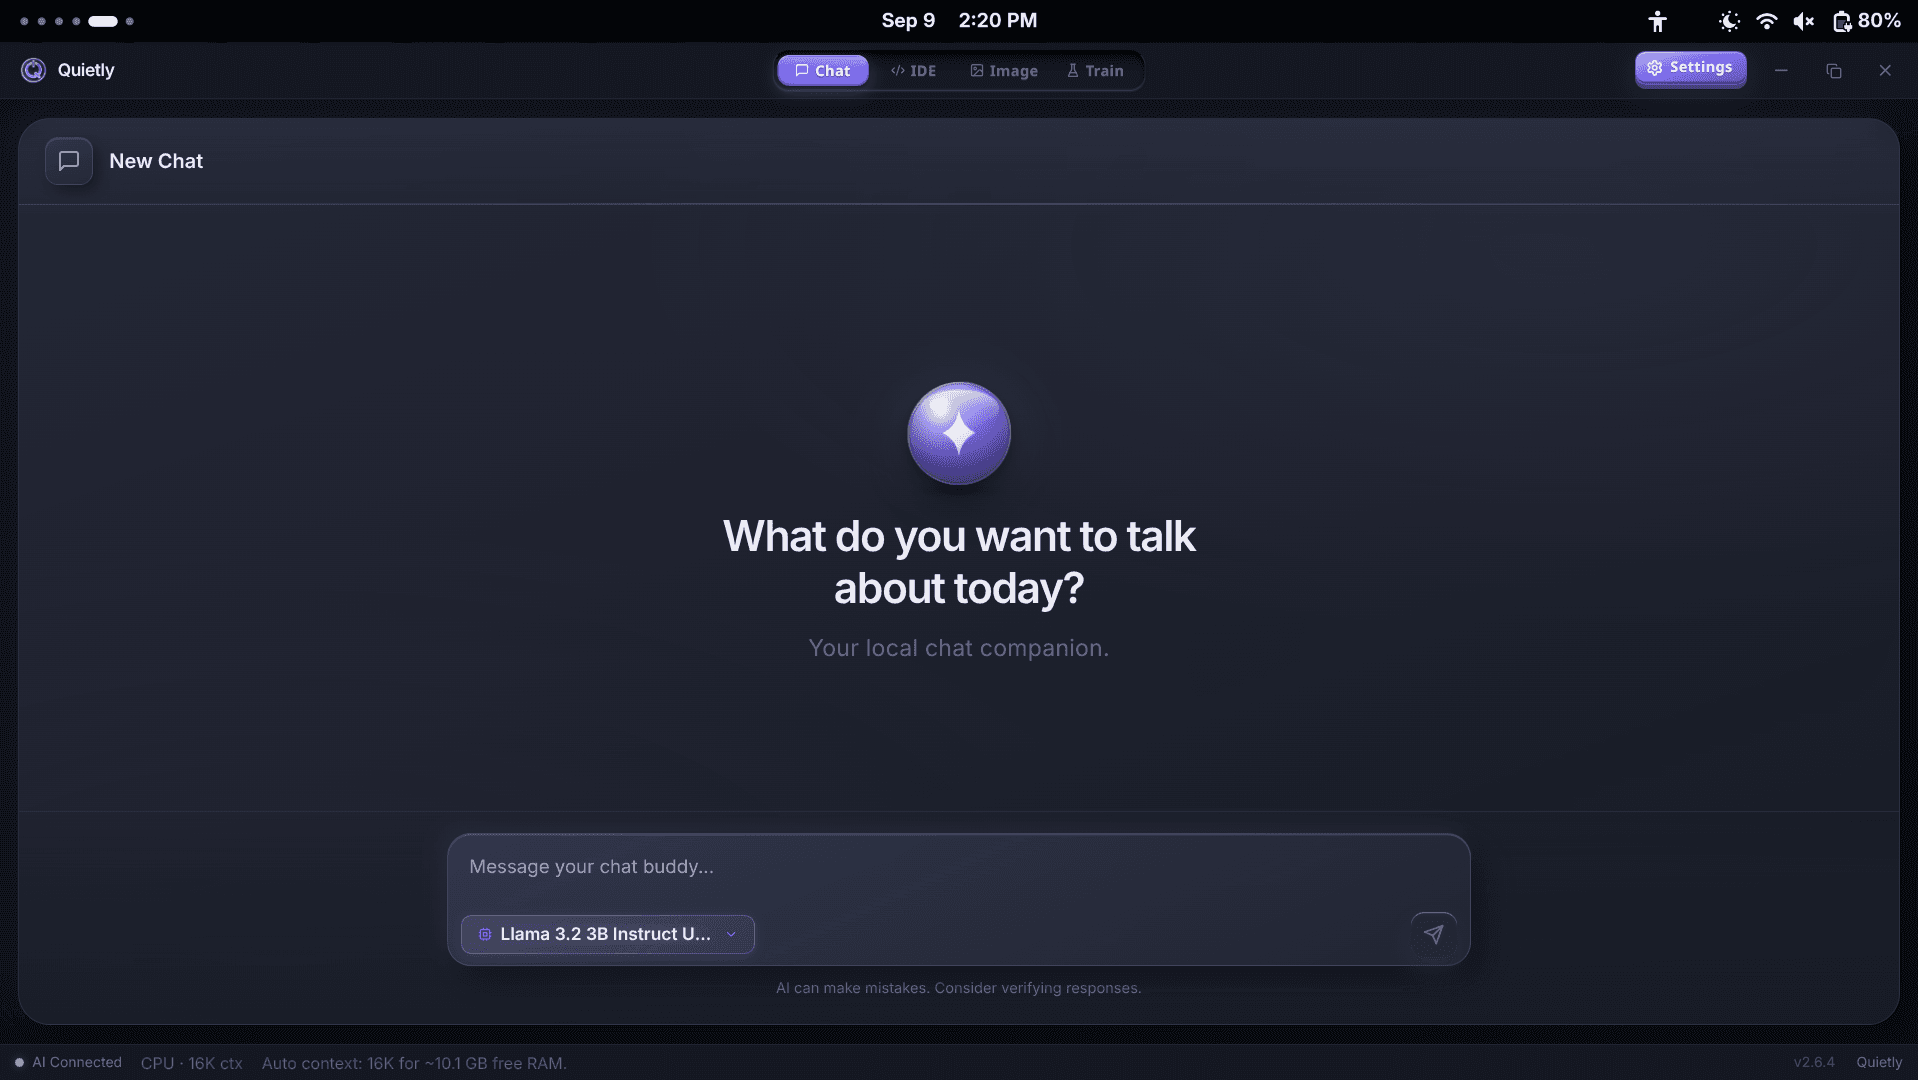
Quietly handles this automatically. With the context window set to Auto, it looks at your free RAM, the model size, and whether your system is swapping, then picks a safe size (you can see it in the status bar, for example “Auto context: 16K”).
RAM vs GPU memory (VRAM)
- If you have a dedicated GPU, VRAM matters most. A model that fits fully in VRAM is many times faster than on the CPU.
- If it only partly fits, the engine can split layers between GPU and RAM. It works, but speed drops.
- Without a GPU, everything runs from system RAM on the CPU. Smaller models (3–4B) are the sweet spot.
- Apple Silicon Macs share memory between CPU and GPU. Roughly 75% of total RAM is usable for the model, so a 16 GB Mac behaves like a ~12 GB GPU.
For GPU-specific numbers, read our VRAM guide at quietlycode.org/blog/vram-guide-local-coding-models-8gb-16gb-24gb.
RAM speed matters more than you think
Having enough RAM decides whether a model runs. How fast your memory is decides how quickly it types. Each new word requires reading most of the model from memory, so memory bandwidth sets the speed limit.
- Rough upper limit: tokens per second ≈ memory bandwidth ÷ model size.
- A laptop with dual-channel DDR4 (~50 GB/s) running a 4.7 GB model tops out around 10 tokens per second, and is usually a bit slower in practice.
- Single-channel RAM (one stick) can halve that—two matched sticks really help.
- Apple Silicon and modern GPUs have much higher bandwidth, which is why they feel so fast.
How to check your own computer
- Windows: Task Manager → Performance → Memory (and GPU for VRAM).
- macOS: Apple menu → About This Mac shows total memory.
- Linux: run free -h in a terminal.
- Or skip all of that: open Quietly → Settings → Engine → Device scan and click “Scan my device.” It also suggests CPU threads and a starting context size.
note
Too little RAM for the model you want?
Quietly’s AirLLM engine can run very large Hugging Face models by streaming them layer by layer from disk. It is slow—think minutes per answer—but it lets big models run on modest machines when quality matters more than speed.
FAQ
Is 8 GB of RAM enough to run an LLM?
Yes, for small models. 1–4B models such as Llama 3.2 3B, Qwen 2.5 3B, Gemma 3 4B, or Phi-4 Mini run well on 8 GB and are great for chat, summaries, and simple coding help. 7B models fit only tightly, with other apps closed.
Is 16 GB of RAM enough for local AI?
16 GB is the sweet spot for most people. It comfortably runs 7–8B models like Qwen 2.5 Coder 7B or Llama 3.1 8B at 4-bit, with room for your OS and a decent context size.
How much RAM do I need for a 70B model?
At 4-bit, a 70B model file is around 40 GB, so you want 64 GB of RAM or more (or several GPUs). Quietly’s AirLLM engine can stream 70B-class models from disk on smaller machines, but very slowly.
Does context length use more RAM?
Yes. The KV cache grows with context. On an 8B-class model, an 8K context adds about 1 GB and 32K adds about 4 GB. Quietly’s Auto context setting picks a size that fits your free memory.
Is RAM or GPU more important for local LLMs?
If you have a dedicated GPU, VRAM matters most for speed. Without one, system RAM decides which models you can run, and RAM speed decides how fast they respond.
Related guides
Awareness
Best Local LLM for Laptops Without a GPU (8 GB / 16 GB RAM) — 2026 Picks
No graphics card? You can still run useful AI offline. The best local LLMs for CPU-only laptops with 8 GB or 16 GB of RAM, what speed to expect, and simple tweaks that make them faster.
Awareness
How to Run a 70B Model on a Small GPU with AirLLM (Honest 2026 Guide)
AirLLM lets 70B-class models like Llama 3.3 70B run on GPUs and PCs that could never hold them in memory. How layer streaming works, what speed and disk space to really expect, and how to set it up without the terminal.
Awareness
llama.cpp GUI for Beginners: Run Local AI Without the Terminal
llama.cpp is the engine behind most local AI—but it’s a command-line tool. Here’s what it does, what all those flags mean, and how to use it through a simple GUI without typing a single command.